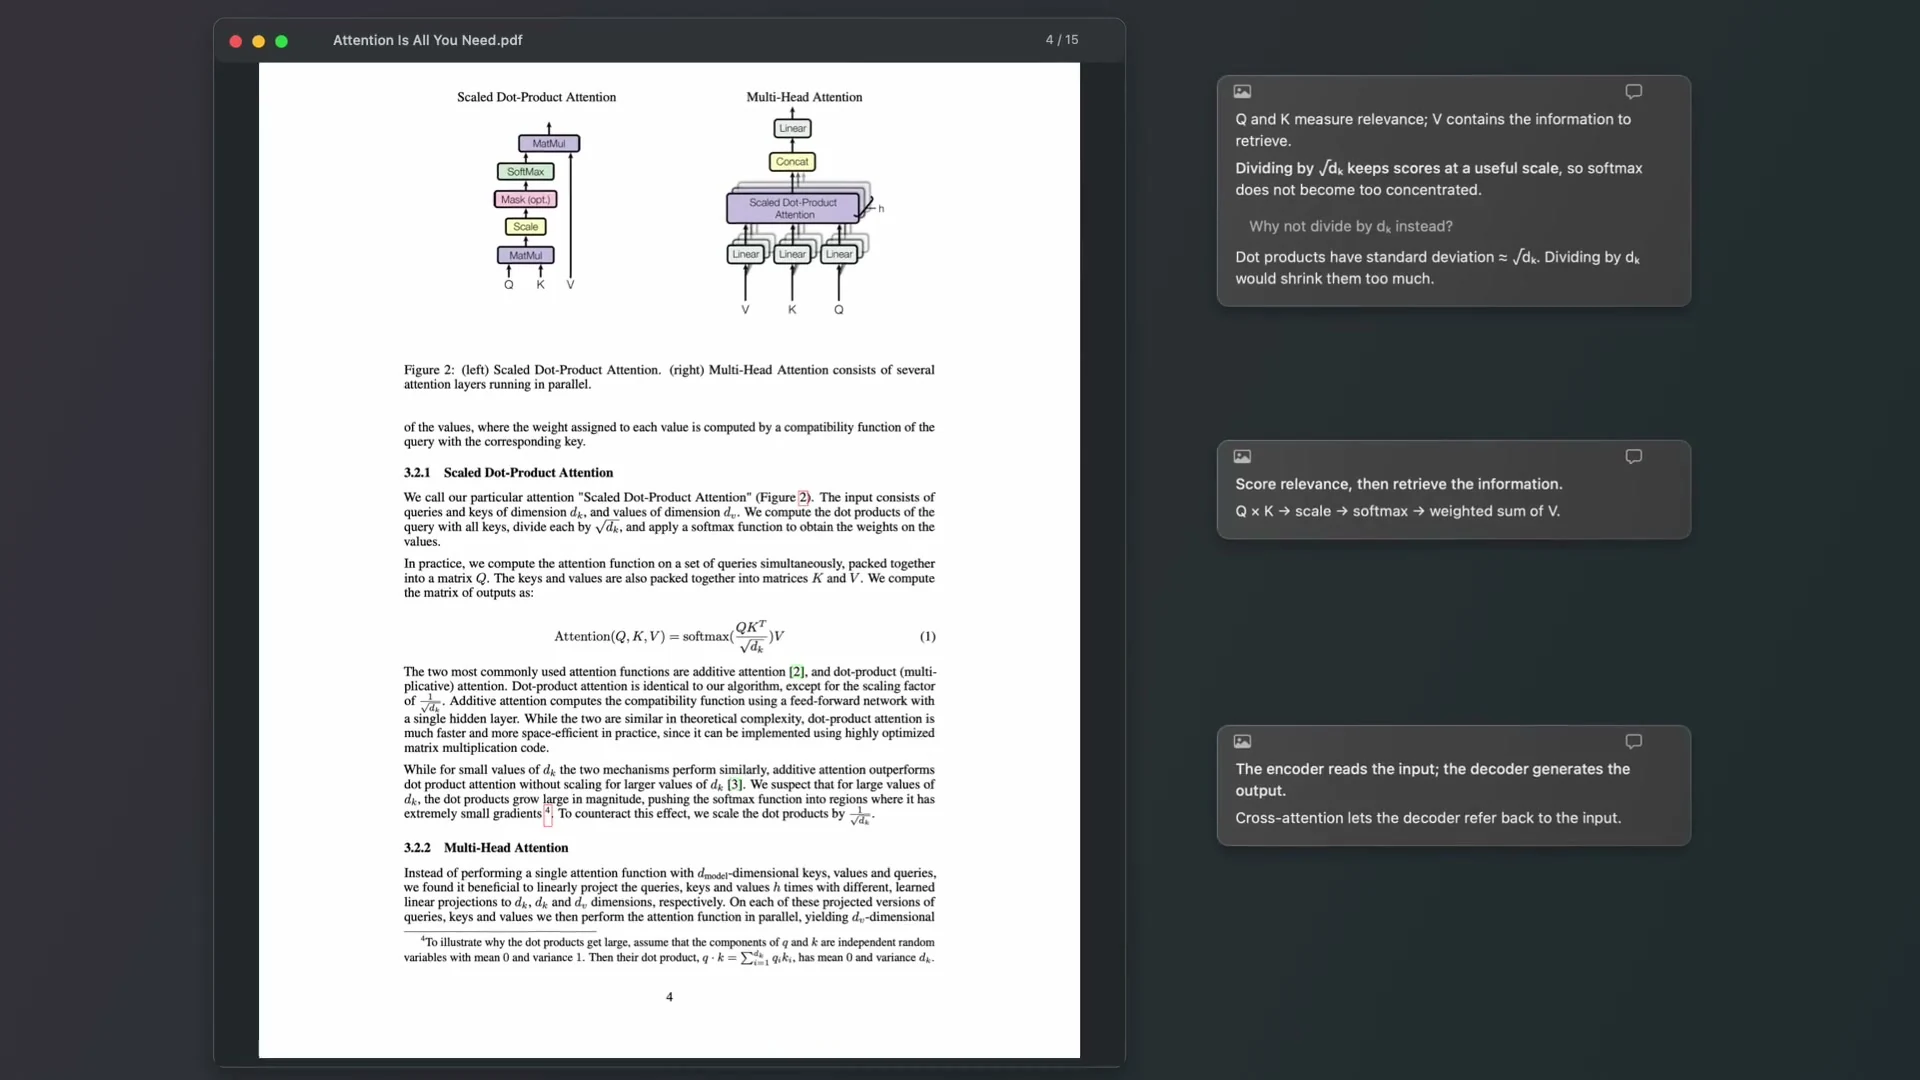
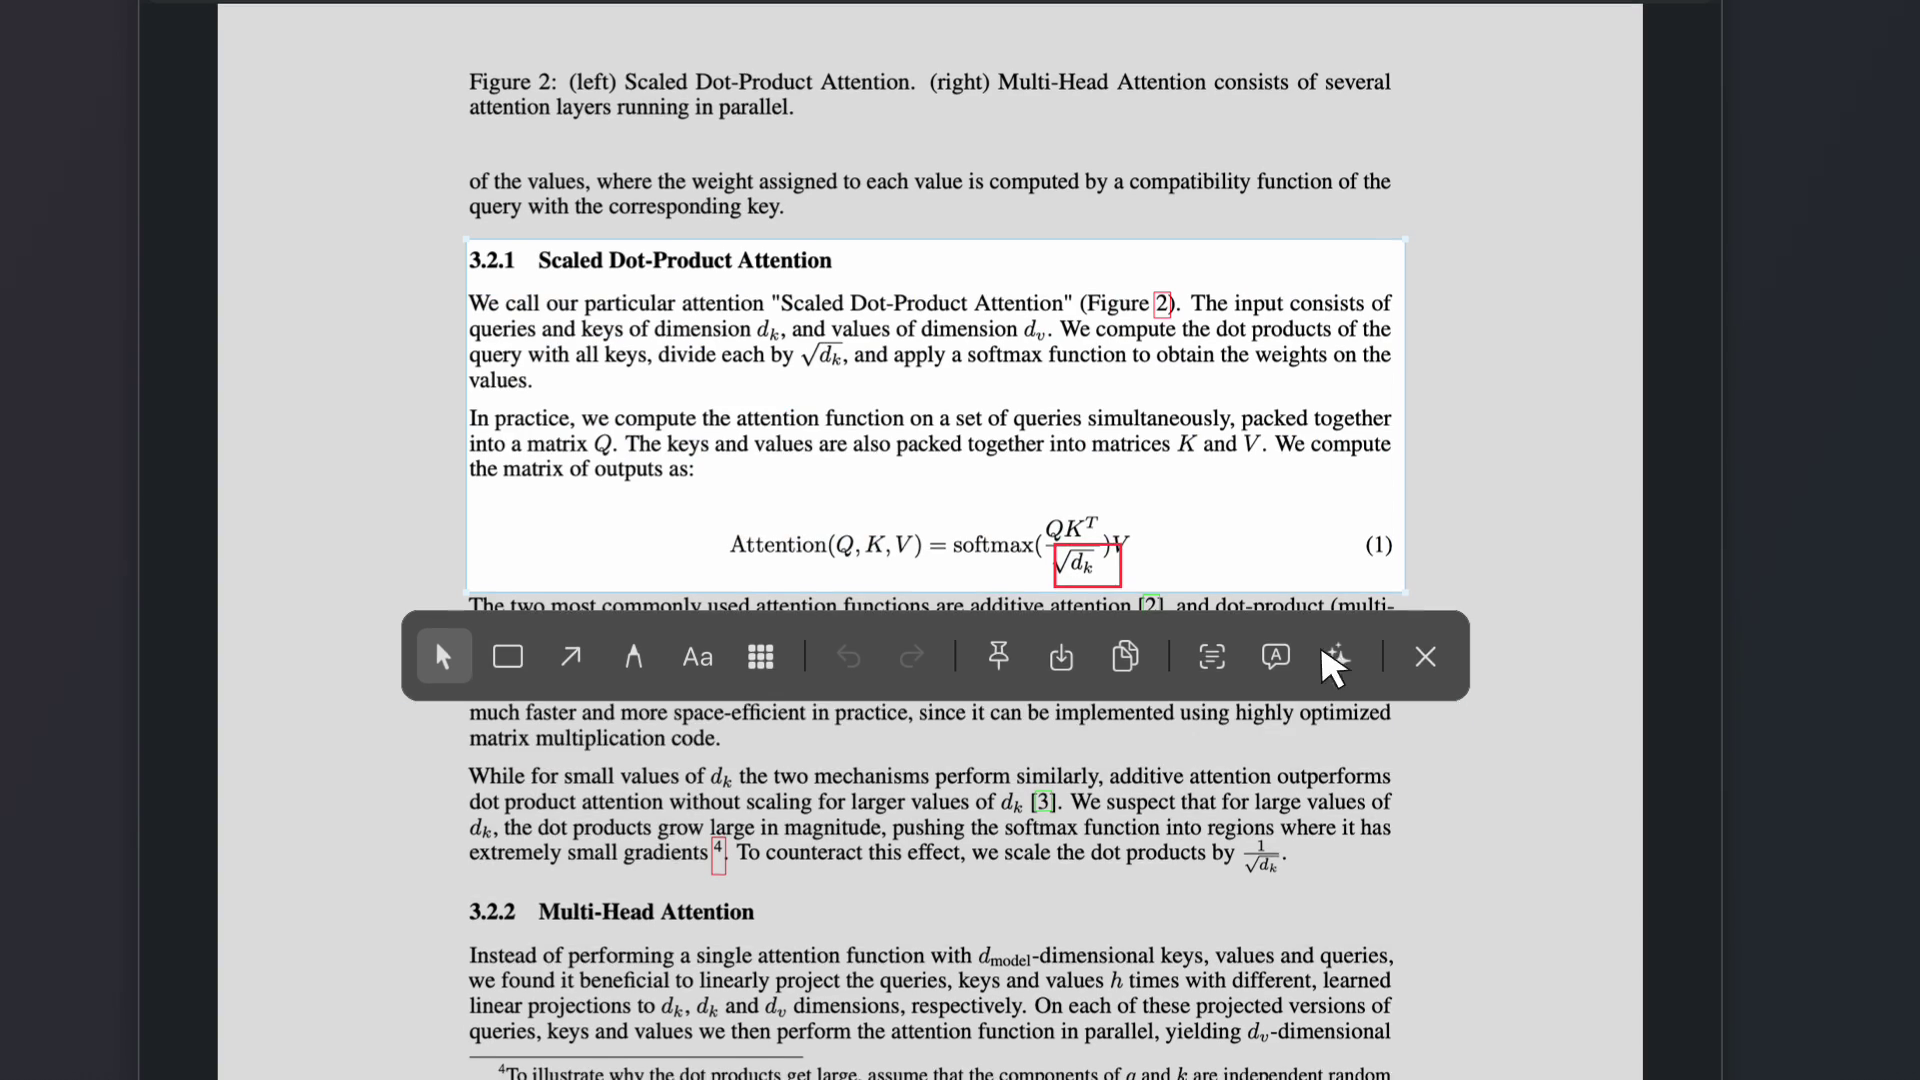
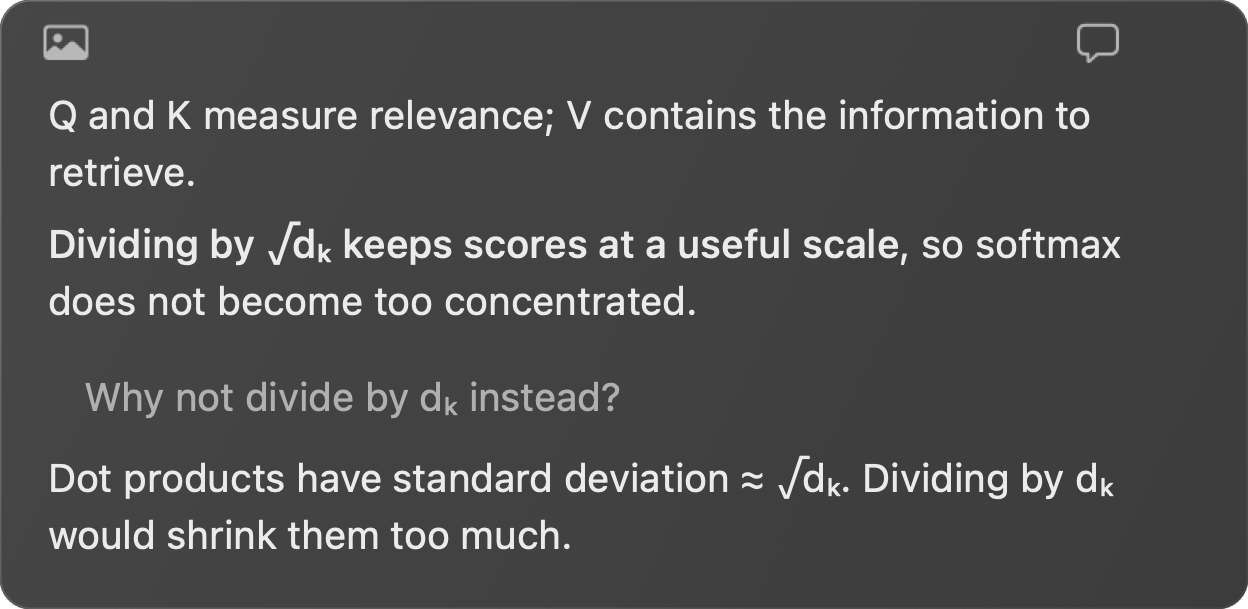
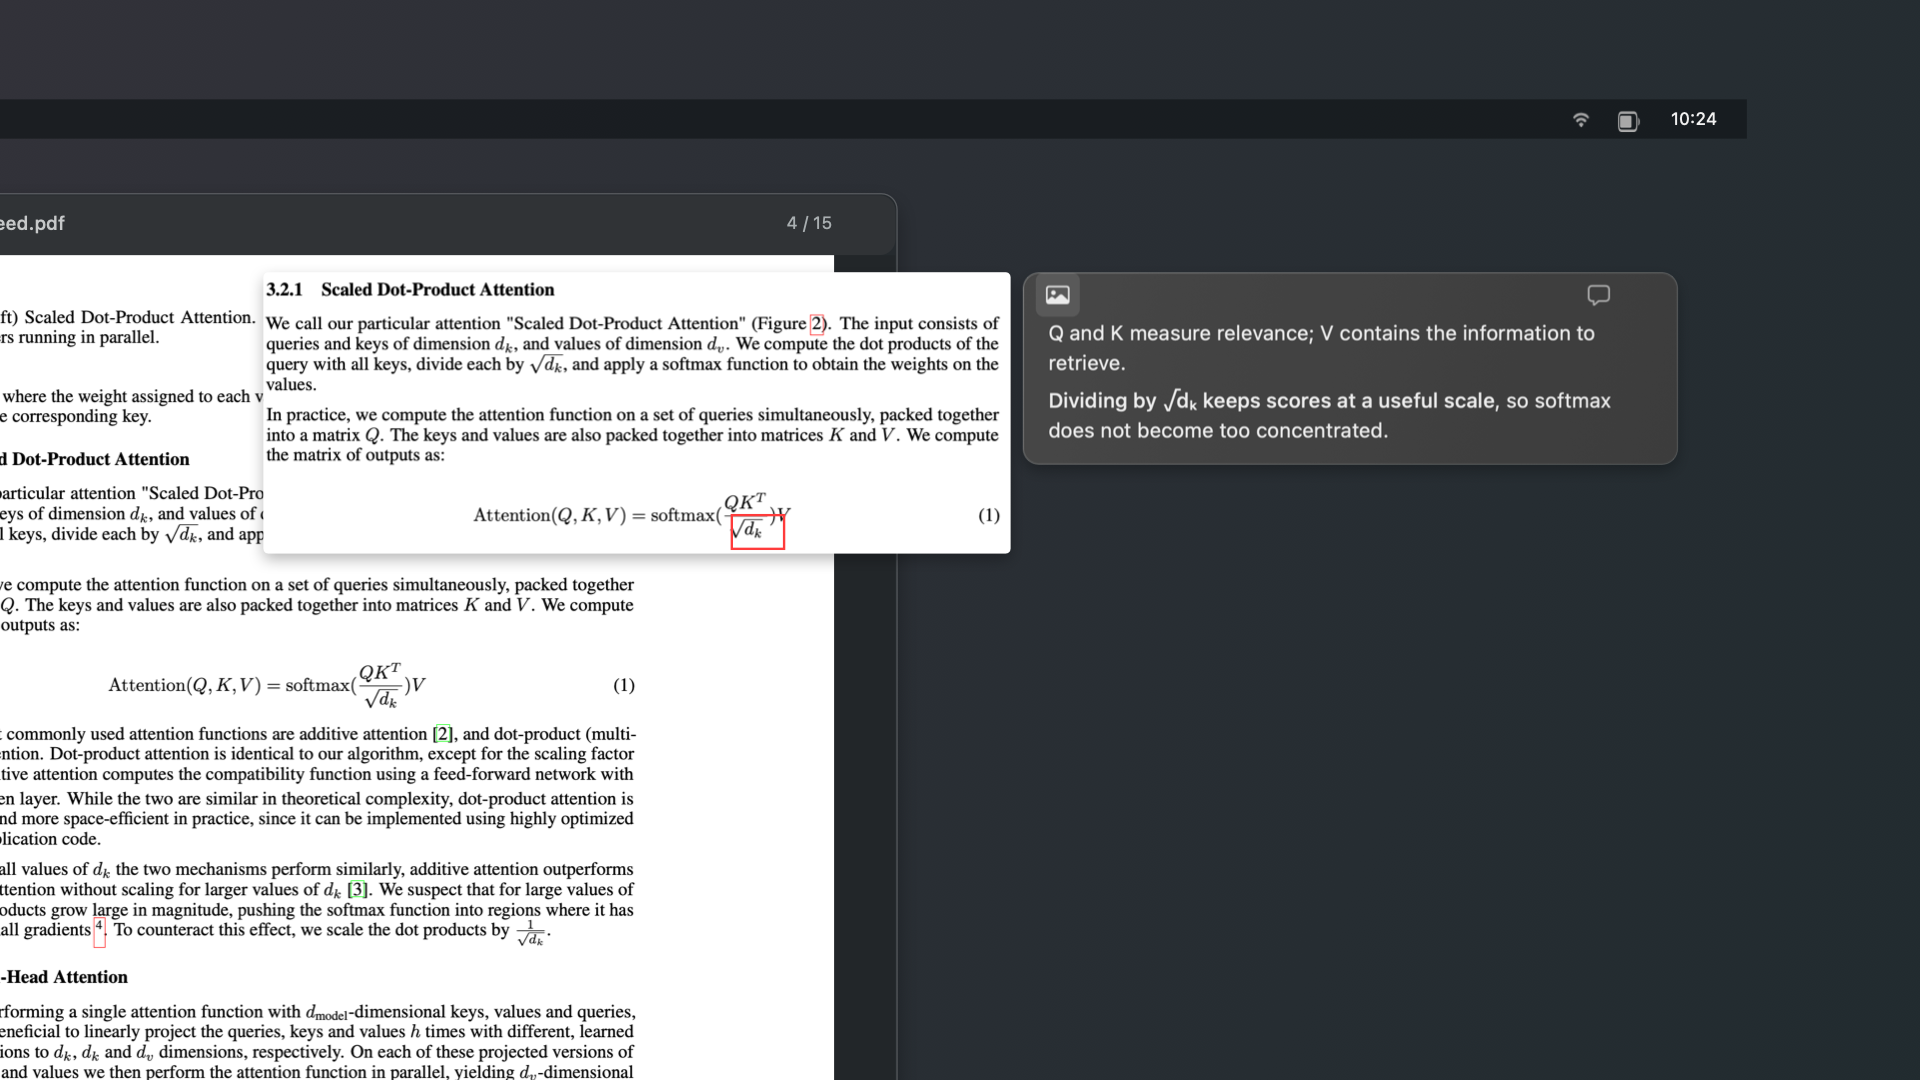
Q and K produce relevance scores; V supplies the information to retrieve. Dividing by √dₖ keeps the scores in a useful range so softmax does not become too concentrated.
Why not divide by dₖ instead?
The dot product has variance of about dₖ, so its standard deviation grows like √dₖ. Dividing by √dₖ offsets that growth; dividing by dₖ would shrink the scores too much.
What does that look like when dₖ is 64?
√64 = 8. A Q·K score of 16 becomes 16 ÷ 8 = 2. Softmax then turns the scaled scores into weights for combining the values in V.
Does scaling change which position is most relevant?
No. Dividing every score by the same positive number preserves their order. It changes how concentrated the softmax weights are, not which position has the highest score.
この会話の文脈を引き継ぎます
Q describes what a position is looking for, K provides features to match against, and V holds the information that will be retrieved.
Is retrieval a useful analogy?
Yes: Q is the query, K helps score the relevant entries, and V is the information returned. Attention combines several values with weights instead of retrieving only one.
Why not use K as V as well?
The clues used for matching and the information returned need not be identical. Separate projections let the model learn those two roles independently.
Can one token produce Q, K and V?
Yes. In self-attention, the same input passes through three learned projections to produce Q, K and V, each with its own role.
この会話の文脈を引き継ぎます
Softmax converts scores into nonnegative weights that sum to one. Positions with higher scores receive larger weights.
Why multiply by V at the end?
The weights determine how much information to take from each position. Multiplying by V produces the weighted combination used as the attention output.
What happens if two scores are equal?
With exactly two positions and equal scores, each receives a weight of 0.5. The output is the average of the two value vectors.
What if one score is much higher?
Its weight moves closer to one while the other moves closer to zero. The output therefore becomes more similar to the value at the high-scoring position.
この会話の文脈を引き継ぎます
 Stillpin